
Compare Classifications by ID After a Rule Change
Generate a human reviewable diff before deciding whether to release the rule.
Use caseUse stable IDs to find changed, missing, and added rows after a rule update
Compare two outputs by record ID before replacing a rule, prompt or model version.
Source · JevLog original · Original guide
2026-09-21 · Editorial update; no live model call
Problem
Section titled “Problem”You changed a category definition and the new output looks cleaner. That alone does not show improvement. First identify exactly which records changed, disappeared or were added. Then evaluate those changes against answers that people have checked.
Before you begin
Section titled “Before you begin”- Two CSVs with unique, nonempty id values and a label column.
- Use the included before.csv and after.csv to understand the report.
Sources
Section titled “Sources”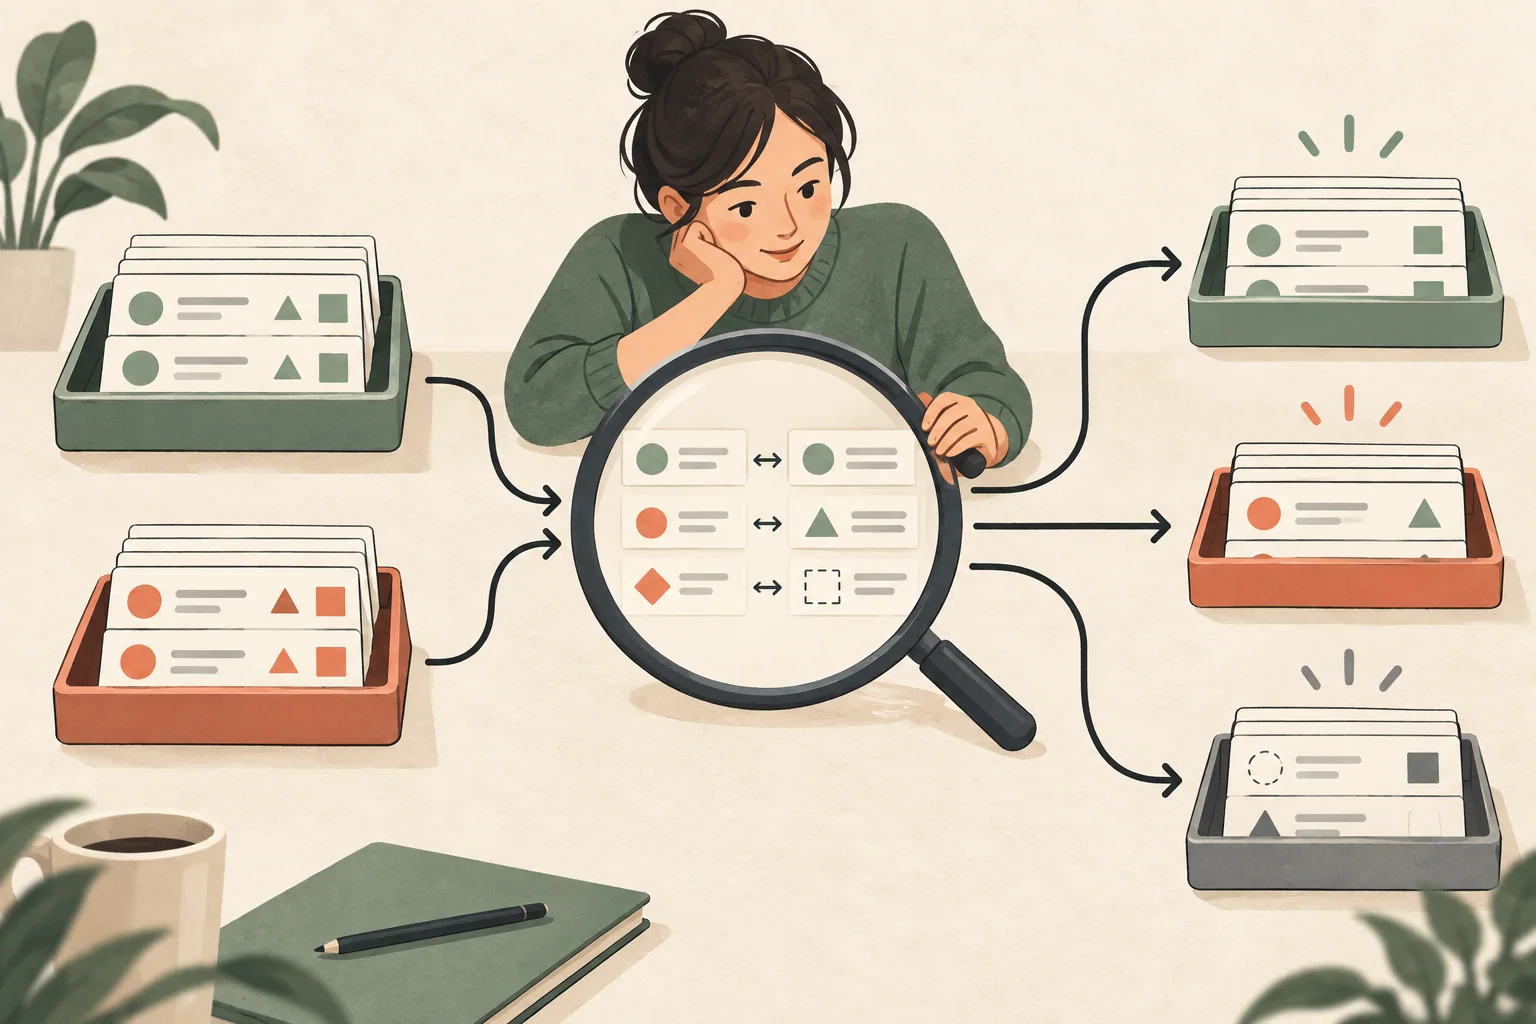
Compare two classification runs and review changed, added, and missing rows. AI concept art.
1. Keep identities stable
Section titled “1. Keep identities stable”Use the same record IDs across runs. Do not join by row number after sorting or dropping rows. The script rejects duplicate IDs, so a data error cannot quietly hide one result behind another.
2. Compare the two fixture files
Section titled “2. Compare the two fixture files”The command writes only changed, added or missing records to a new file. It refuses to overwrite existing output.
python scripts/compare_runs.py examples/before.csv examples/after.csv --output changes.csv3. Read the three kinds of differences
Section titled “3. Read the three kinds of differences”In the fixture, ID 2 has a changed label, ID 3 is missing and ID 4 is new. A missing record may indicate a failed export rather than a model decision. Investigate it separately.
4. Decide which differences are acceptable
Section titled “4. Decide which differences are acceptable”Open the original text and reference label for changed records. Record why a new result is better or worse. A change report intentionally has no accuracy score because it contains no independently labeled truth.
5. Store the configuration alongside the result
Section titled “5. Store the configuration alongside the result”Keep the criteria, selected input column, model identifier, date and evaluation set version. Download Studio’s setup JSON as an example of storing the non-sensitive configuration. Live production runs need a server-side audit and deployment process.
Practice sample: download before.csv (CSV Studio / local practice; not a live run here).
Check the result
Section titled “Check the result”A compact difference file containing three records for the fixture. It shows what changed, not whether the new version should be shipped. Run a separate evaluation on held-out human labels before making that decision.
- You can identify the input, its source, and the fields that leave your system.
- Original identities, failed rows, uncertain cases and human corrections remain visible.
- You distinguish an offline fixture, an author demo and a live evaluation you ran yourself.
Continue reading
Section titled “Continue reading”- Send uncertain decisions to a human review queue
- Check your CSV for blanks, repeats, and shifted columns
Does no change mean safe to deploy?
Section titled “Does no change mean safe to deploy?”No. It only describes the compared outputs.