
Route Low-Signal CSV Decisions to Human Review
Create mutually exclusive queues with review reasons that merge back into the source table.
Use caseRoute failures, missing information, and weak signals into separate review queues
Split a normalized results CSV into suggested and review files with an explicit practice threshold. Check every ID and review reason, then let a person confirm the final label.
Source · JevLog original · Original guide
2026-09-21 · Editorial update; no live model call
Problem
Section titled “Problem”Four synthetic results include low scores or missing data. Supply a practice threshold, split them into suggested and review files, and check that every source ID appears once. Read each review reason before human confirmation. The sample 0.8 threshold is neither a Jev measurement nor a general policy.
Before you begin
Section titled “Before you begin”- Use the provided synthetic normalized_results.csv first.
- Its confidence values are invented fixtures for testing code, not Jev measurements.
Sources
Section titled “Sources”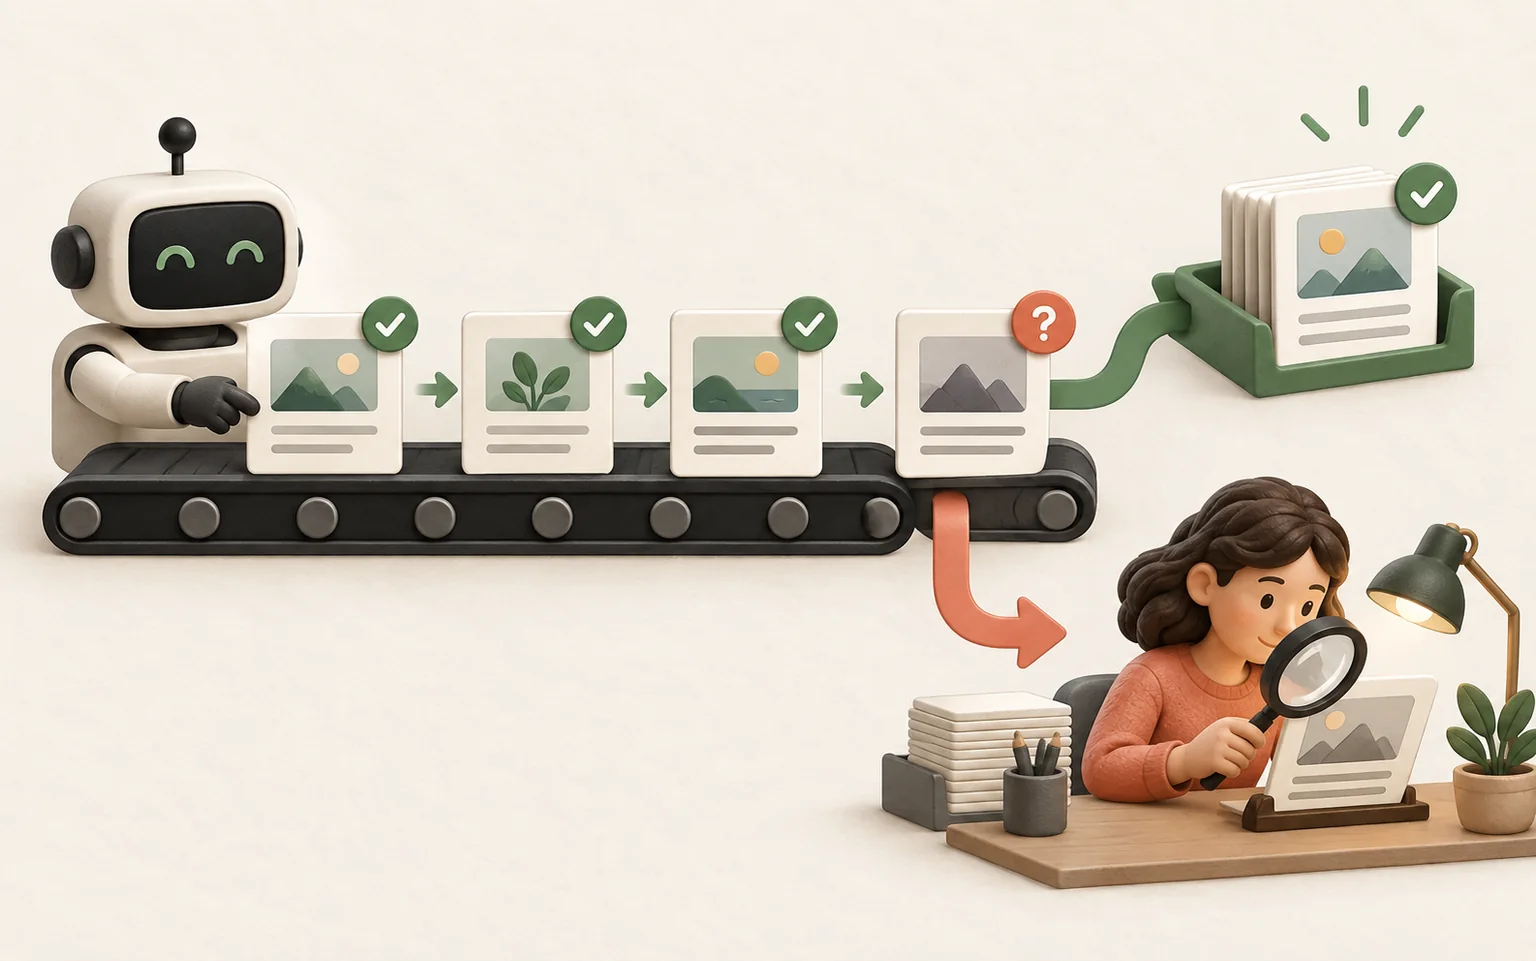
Low-signal, incomplete, or failed results enter a human review queue. AI concept art.
1. Define the normalized columns
Section titled “1. Define the normalized columns”Map real output to id, text, label, and confidence. Check the score definition first; this script does not calibrate or measure accuracy.
2. Choose an explicit test threshold
Section titled “2. Choose an explicit test threshold”Pass –threshold; use 0.8 only for the synthetic example. Missing or invalid scores go to review; the command stays local.
python scripts/split_review_queue.py examples/normalized_results.csv --threshold 0.8 --output-dir review-demo3. Read both outputs
Section titled “3. Read both outputs”Expect two rows per file and all four source IDs. Check review reasons against original text; Suggested is not approved.
4. Make the final decision visible
Section titled “4. Make the final decision visible”Confirm or change labels in Studio and record why. Keep the original suggestion; a team system also needs reviewer and time.
5. Test on fresh examples
Section titled “5. Test on fresh examples”Sample suggested rows too. Use separate labeled examples to balance missed errors against review workload before changing the threshold.
Practice sample: download normalized_results.csv (CSV Studio / local practice; not a live run here).
Check the result
Section titled “Check the result”You can join both files to the source by ID and explain each review decision; this does not measure model accuracy.
- You can identify the input, its source, and the fields that leave your system.
- Original identities, failed rows, uncertain cases and human corrections remain visible.
- You distinguish an offline fixture, an author demo and a live evaluation you ran yourself.
Continue reading
Section titled “Continue reading”Is a lower review rate always better?
Section titled “Is a lower review rate always better?”No. Compare missed errors and human effort together.